
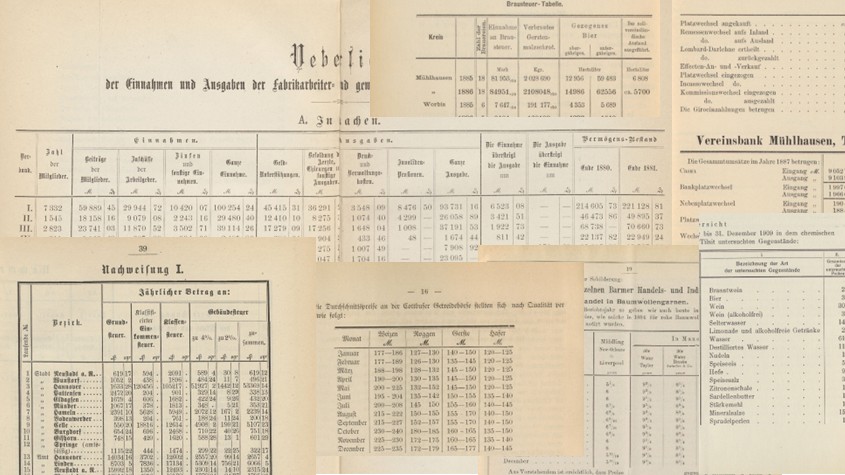
Historical Tables of the Berlin State Library
This dataset of historical tables was compiled from the Digitised Collections of the Staatsbibliothek zu Berlin. It comprises 5,000 images of tables in .png format; the images were derived from 861 documents published between 1500 and 1930.
In document layout analysis (DLA), the detection and classification of multiple classes of layout elements such as text regions, images, tables etc. is required in order to extract and process them in subsequent steps. This proves to be a challenging task in digitised cultural heritage items such as historical books, periodicals and handwritten records, especially with regard to the fact that tables are traditionally predominantly composed of text but with widely varying table layouts over the course of time. Despite all the progress in the fields of computer vision and pattern recognition, the automatic recognition and extraction of the contents of historical tables as structural data continue to pose significant challenges for software solutions.
The primary intention of the publication of this dataset was the provision of a large computationally amenable dataset exclusively consisting of images of tables from historical documents to stimulate research and development of suitable methods and applications. In 2026, a generic automated data extraction tool for (historical) tabular sources still forms a desideratum. In this respect, the dataset provided here aims to make a contribution to filling this gap. The dataset is suitable for the computational use of digitised collections according to the Collections as Data principles.
If you want to work with this dataset, please get in touch at lab@sbb.spk-berlin.de.
 bpk / Kunstbibliothek, SMB, Photothek Willy Römer / Willy Römer